

Lmaana 2.2
Lmaana 2.2 is a Moroccan Darija automatic speech recognition model built by fully fine-tuning OmniASR CTC 3B v2 with a CTC objective. It was trained on Dataset13 clean v4 with two-node FSDP and evaluated with greedy CTC decoding.
The released checkpoint is step_10000, the final checkpoint in the planned
training schedule. All validation and test results below were computed with
this reproducible saved checkpoint.
Model summary
| Field | Value |
|---|---|
| Release | Lmaana 2.2 |
| Base model | OmniASR CTC 3B v2 |
| Adaptation | Full fine-tuning with CTC |
| Target language | Moroccan Darija (ary-Arab) |
| Training data | Dataset13 clean v4 |
| Training setup | Two-node FSDP, one L40S GPU per node |
| Planned training budget | 10,000 steps |
| Released checkpoint | Step 10,000 |
| Tokenizer | OmniASR written tokenizer v2 |
| Decoder | Greedy CTC |
Results
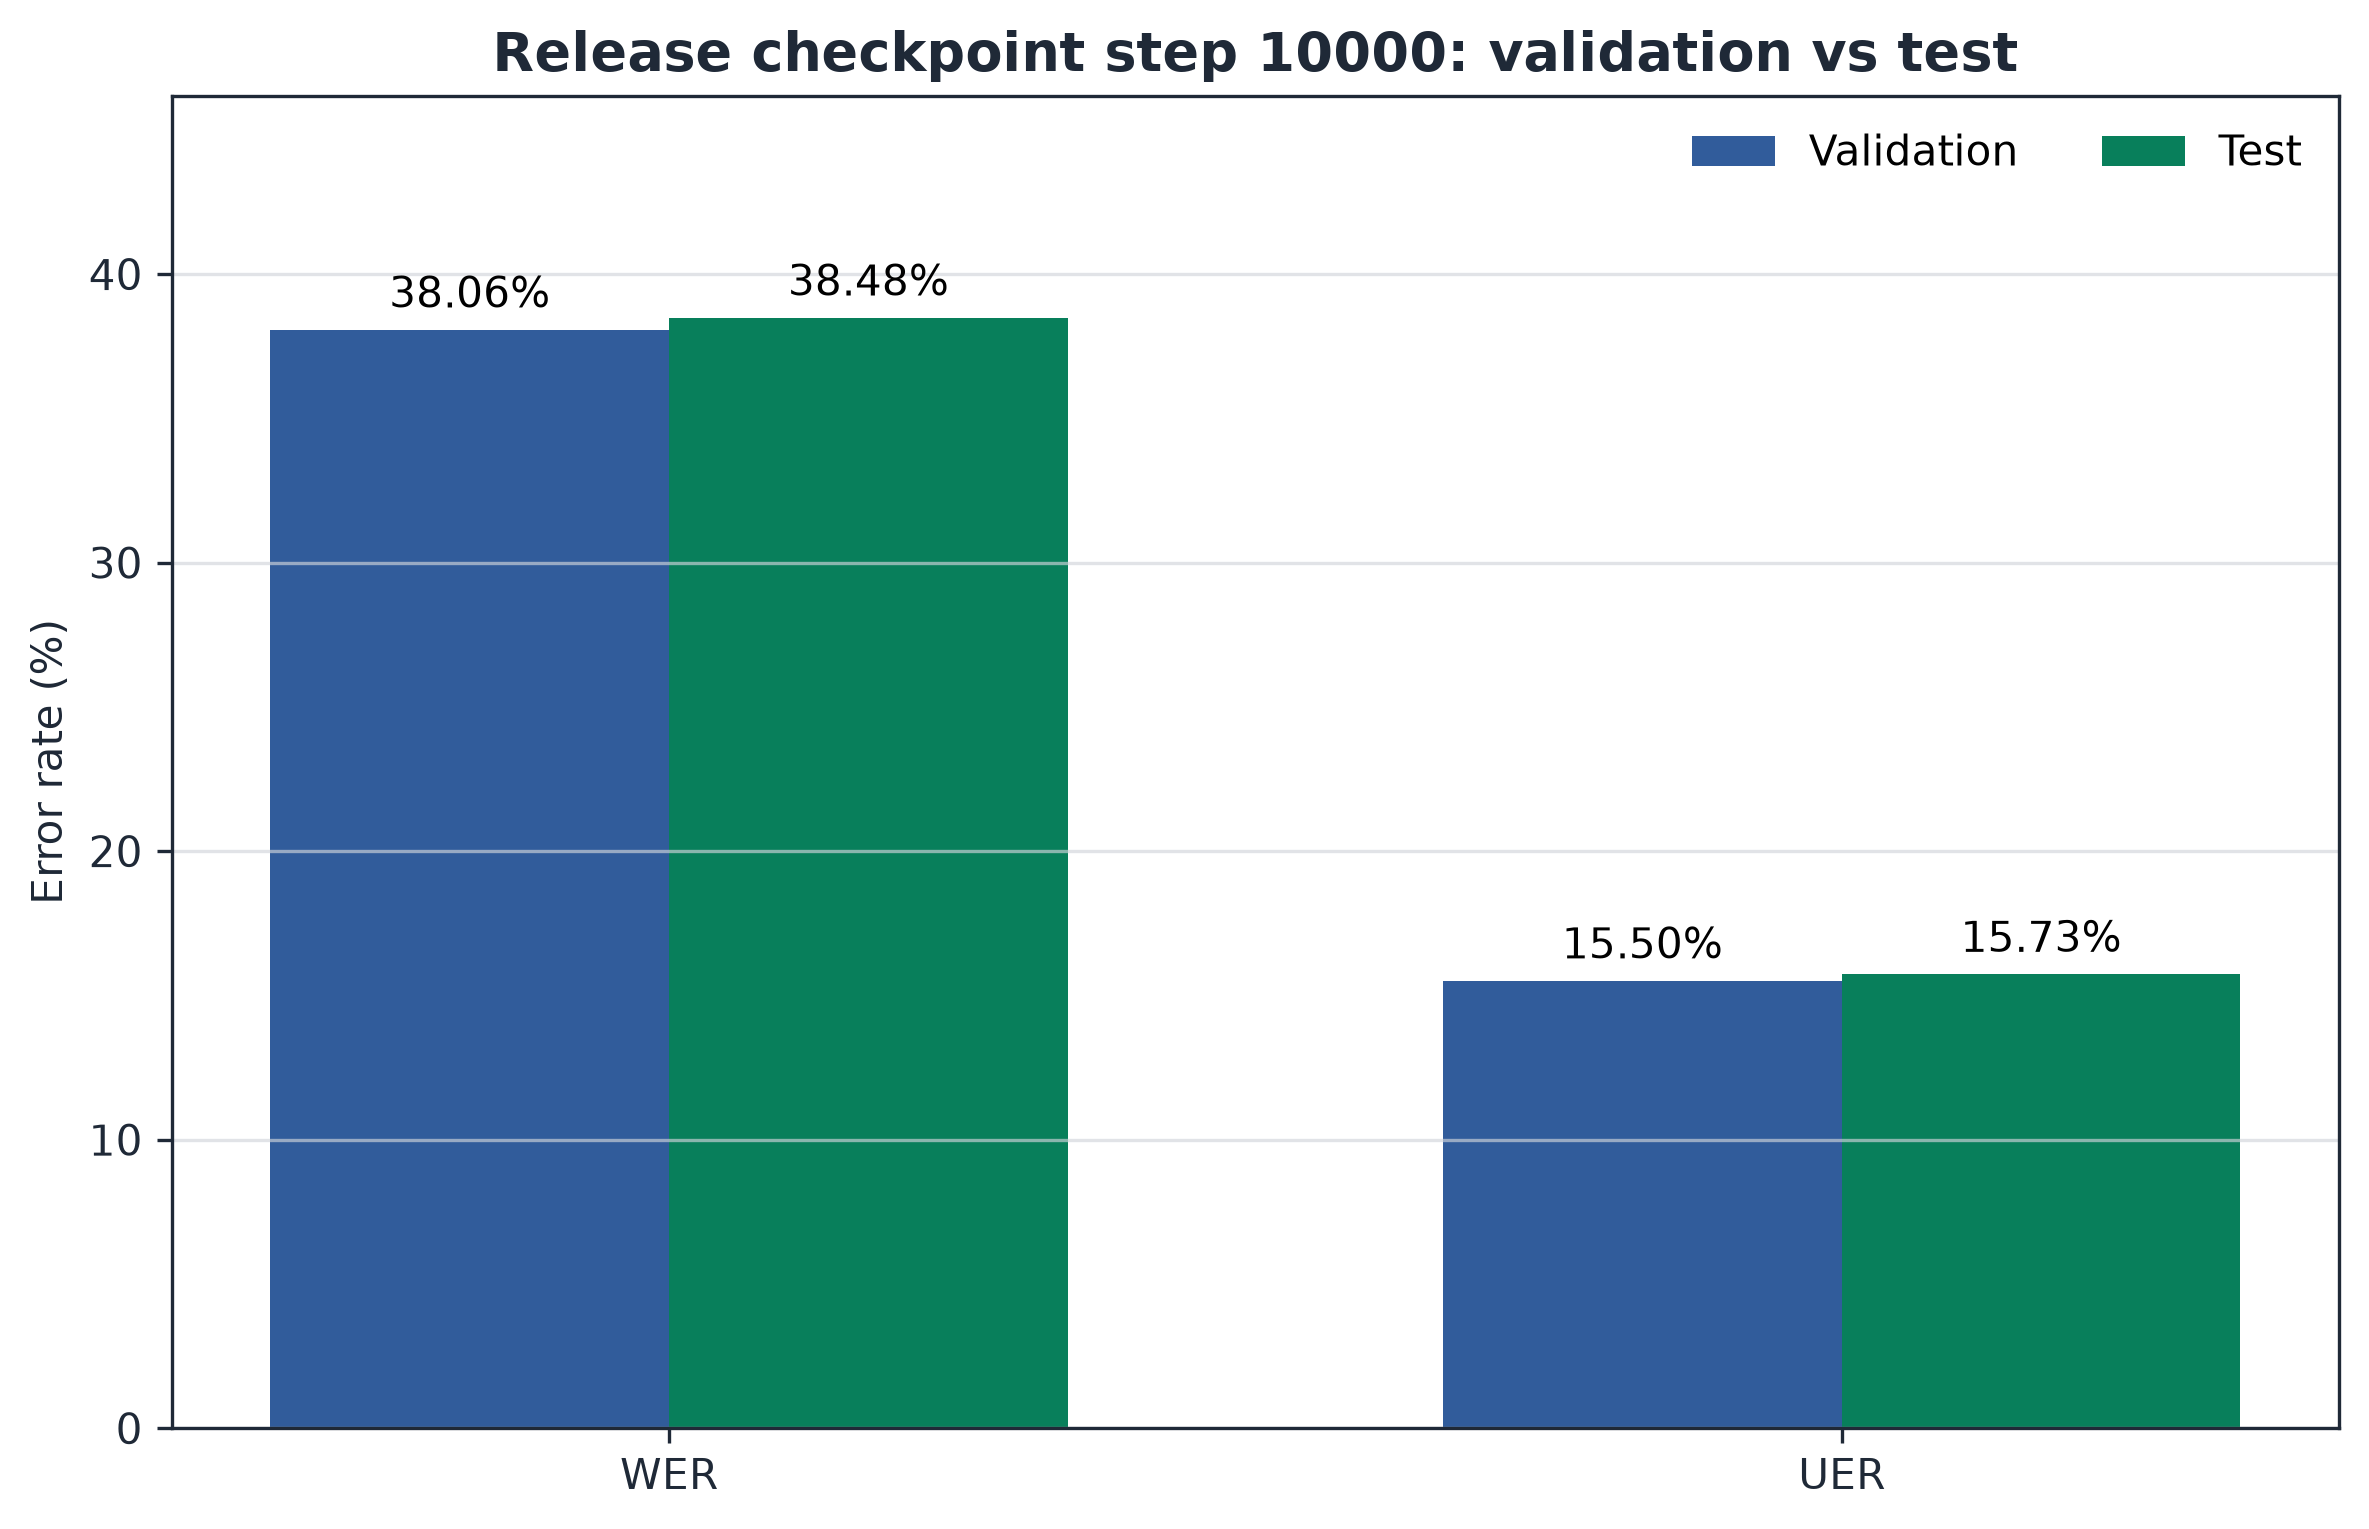
The validation and test sets are disjoint Dataset13 clean v4 splits. UER is the tokenizer-unit error rate reported by fairseq2 and is distinct from CER. Test CER was computed at corpus level from the normalized references and greedy hypotheses after removing whitespace.
| Split | Examples | CTC loss | UER (%) | CER (%) | WER (%) |
|---|---|---|---|---|---|
| Validation | 6,893 | 155.0191 | 15.5020 | Not measured | 38.0618 |
| Test | 6,576 | 160.8470 | 15.7283 | 16.3063 | 38.4762 |
The validation-to-test WER gap is 0.4144 percentage points, which indicates close agreement between the two splits under the same normalization and greedy decoding protocol.
Compared with the previous step_8000 candidate, test WER improved by
0.6869 percentage points, from 39.1631% to 38.4762%.
Training dynamics
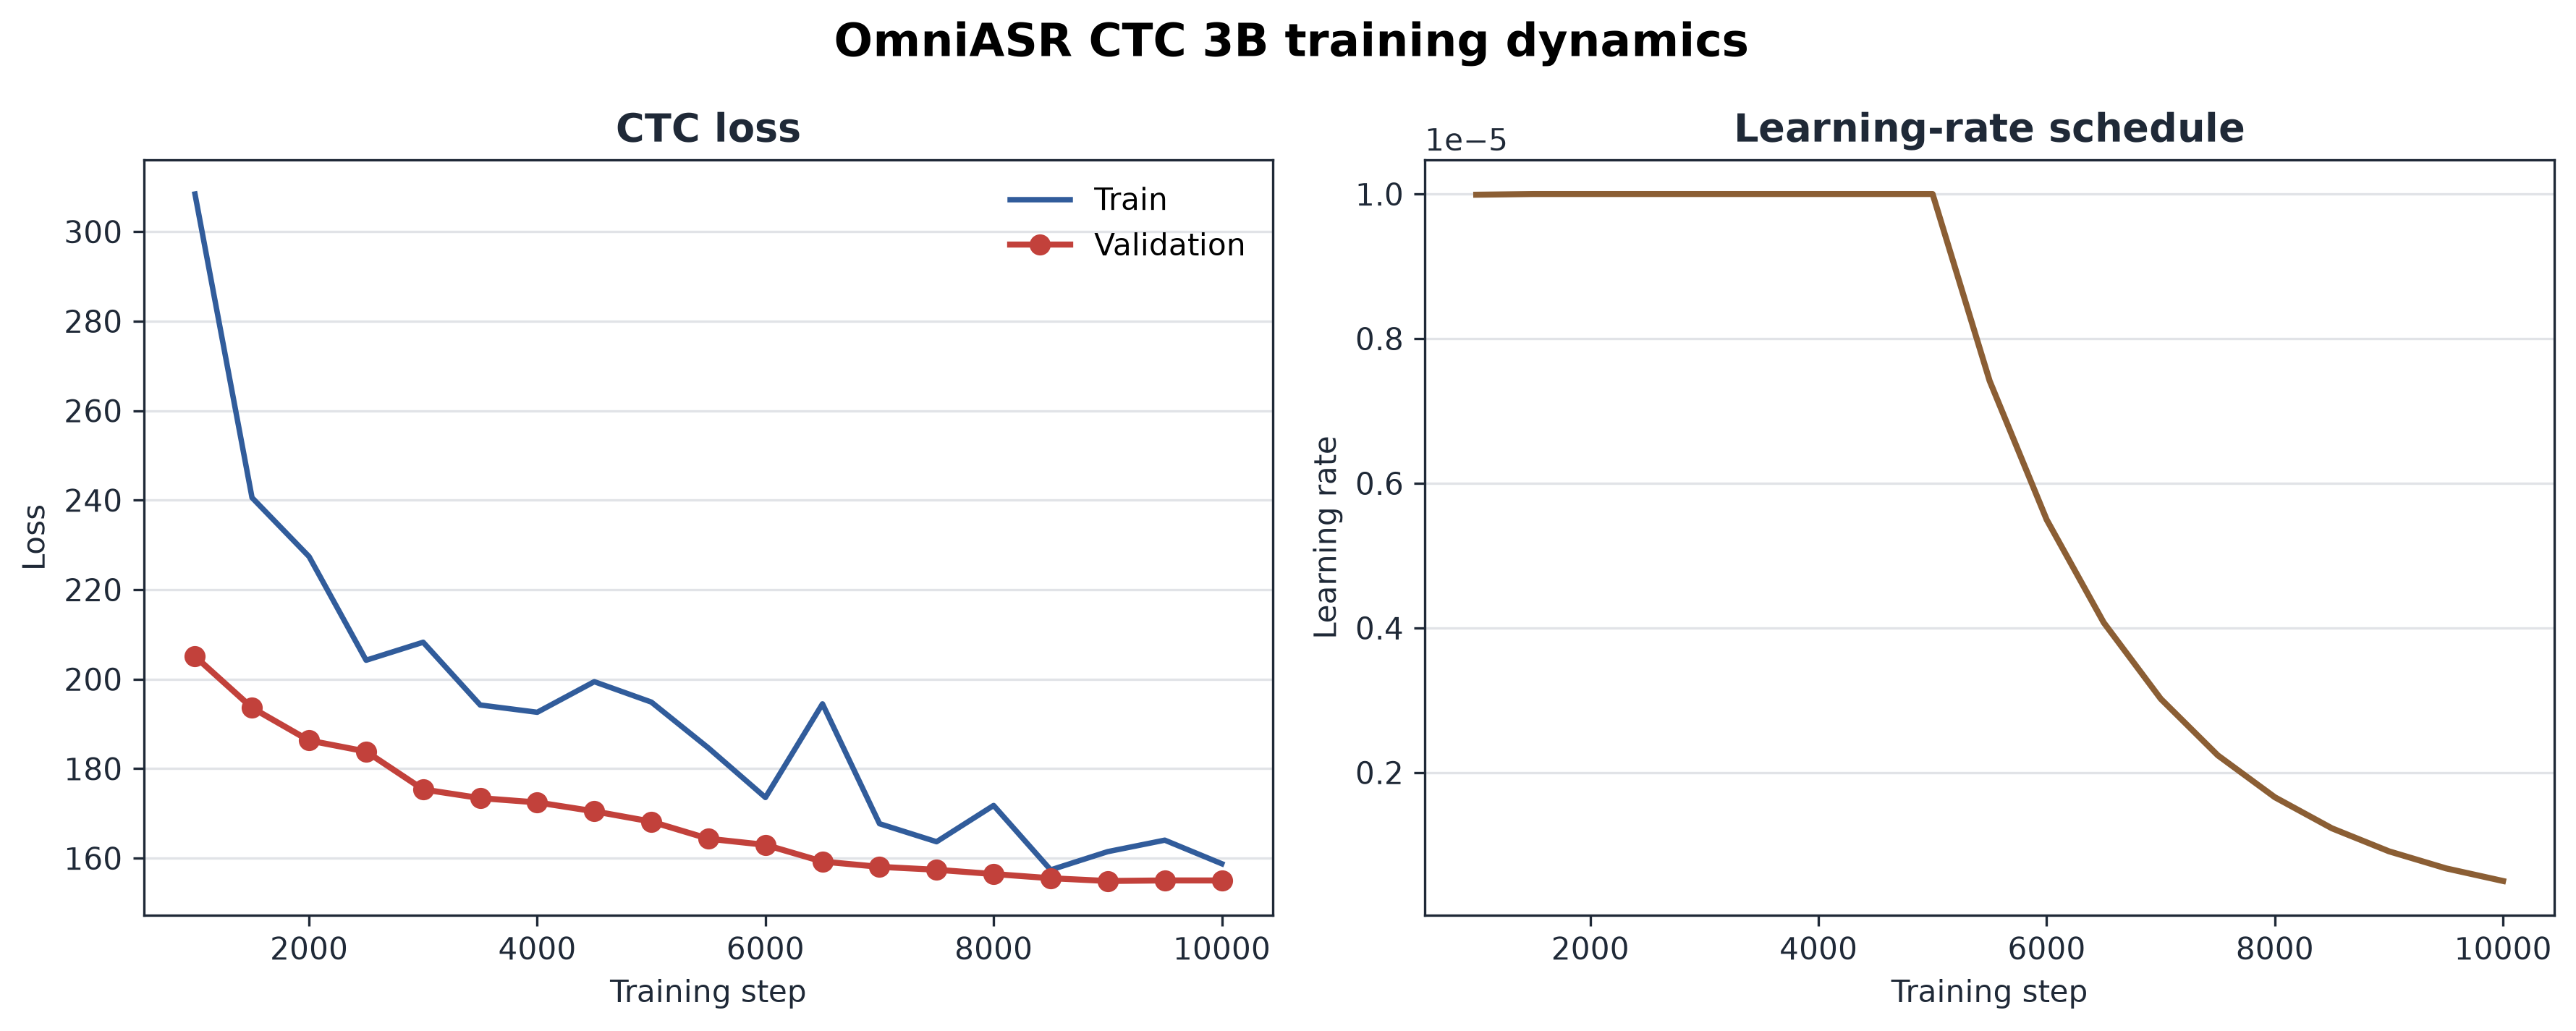
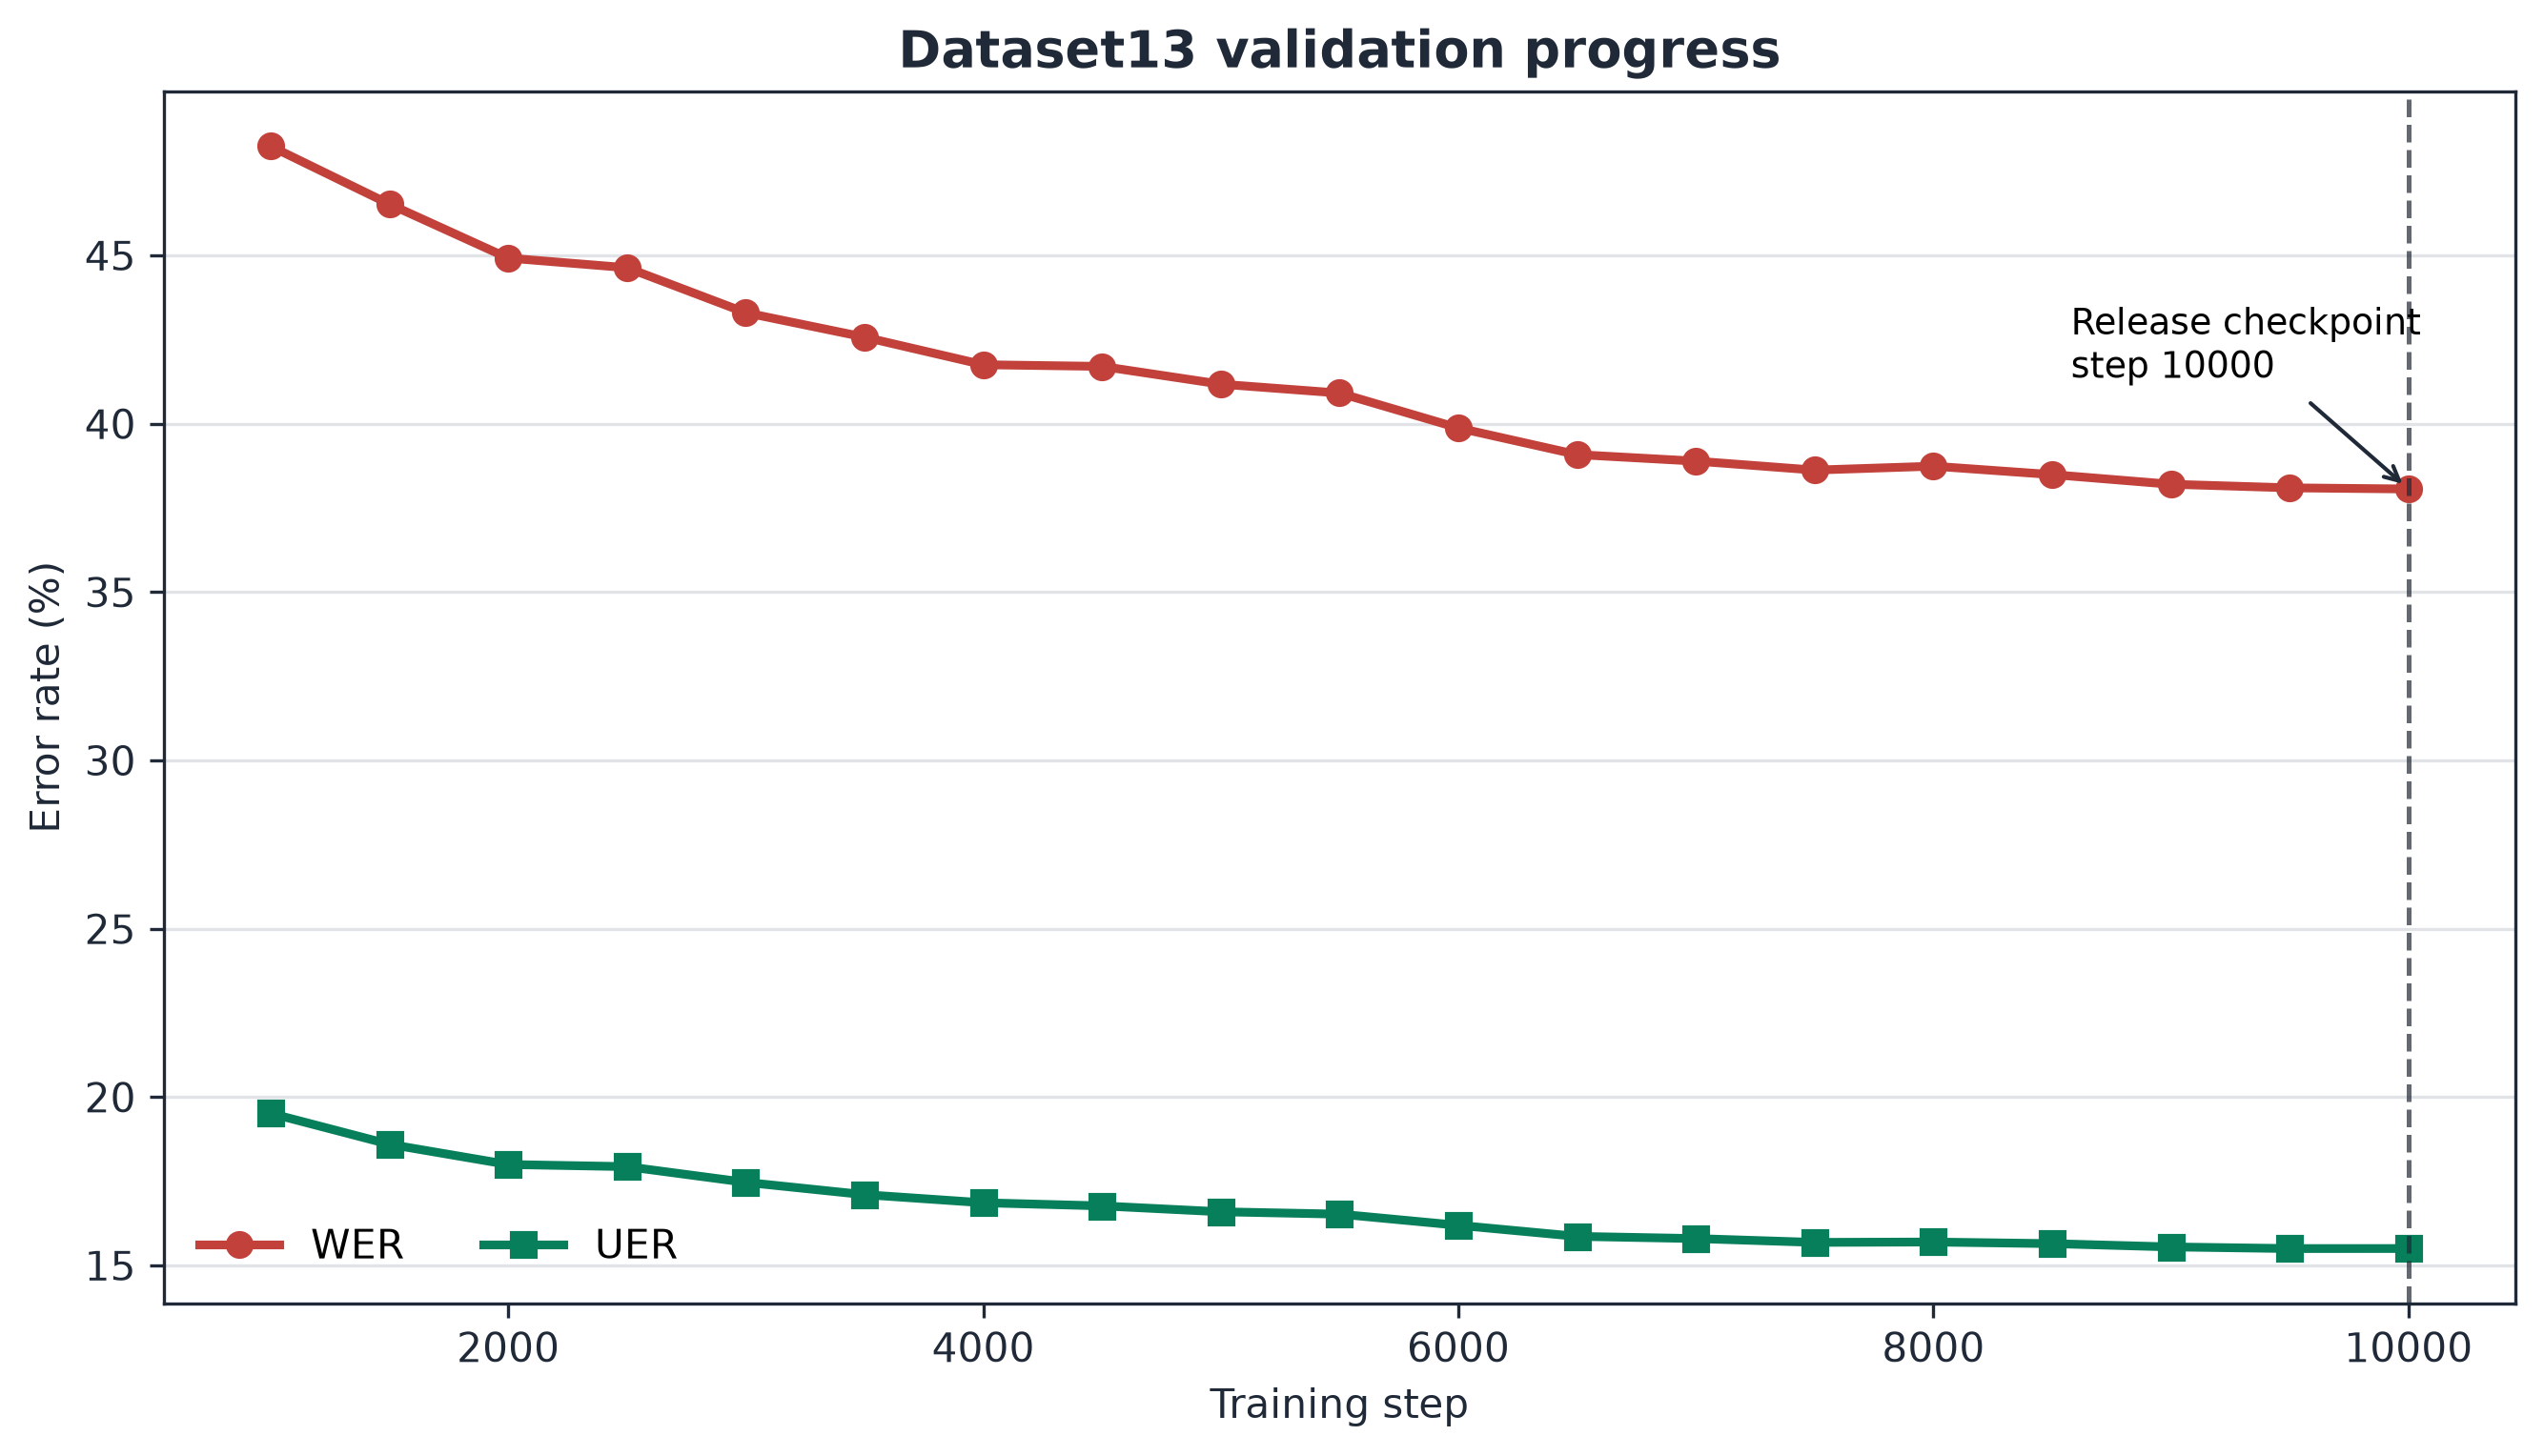
Validation WER decreased throughout the run, from 48.24% at step 1,000 to 38.06% at the final step 10,000 checkpoint. The learning rate began decaying after step 5,000, and no final-stage validation regression was observed.
Intended use
This model is intended for:
- research on Moroccan Darija speech recognition;
- evaluation of CTC-based ASR systems;
- transcription experiments on audio similar to Dataset13;
- reproducible comparison with other Darija ASR systems.
It should not be treated as a certified transcription service, a general Arabic speech recognizer, or a system suitable for high-stakes decisions without task-specific evaluation.
Limitations
- Dataset13 may not represent all Moroccan accents, speakers, recording conditions, or code-switching patterns.
- WER is sensitive to text normalization, spelling conventions, punctuation, and segmentation.
- Performance may degrade on noisy audio, reverberant recordings, children's speech, rare names, and domains absent from training data.
- The model should be evaluated separately on code-switched and non-code- switched subsets before making deployment claims.
Reproducibility
The public research repository contains versioned configurations, the FSDP launcher, the consolidation utility, evaluation recipe, notebooks, and figure generator:
https://github.com/BADR-JOULAlI/darija-asr-v2
The two FSDP model shards were consolidated before single-GPU evaluation. The
released consolidated.pt checksum is:
SHA-256 b22dd8ece46eb24316a96d342f53f8864881b6827ecdec9923006b03ad806471
The original audio data remains outside Git. Reproduction requires authorized access to Dataset13 clean v4 and OmniASR written tokenizer v2.
Base model and data attribution
This work is an adaptation of OmniASR CTC 3B v2. Users must review and comply with the base model license, the Dataset13 terms, and the terms of any other source corpora before downloading or redistributing the weights.
Citation
@misc{lmaana_2_2,
  title  = {Lmaana 2.2: CTC Speech Recognition for Moroccan Darija},
  author = {Skiredj, Abderrahman},
  year   = {2026},
  note   = {Dataset13 clean v4; released checkpoint at step 10000}
}